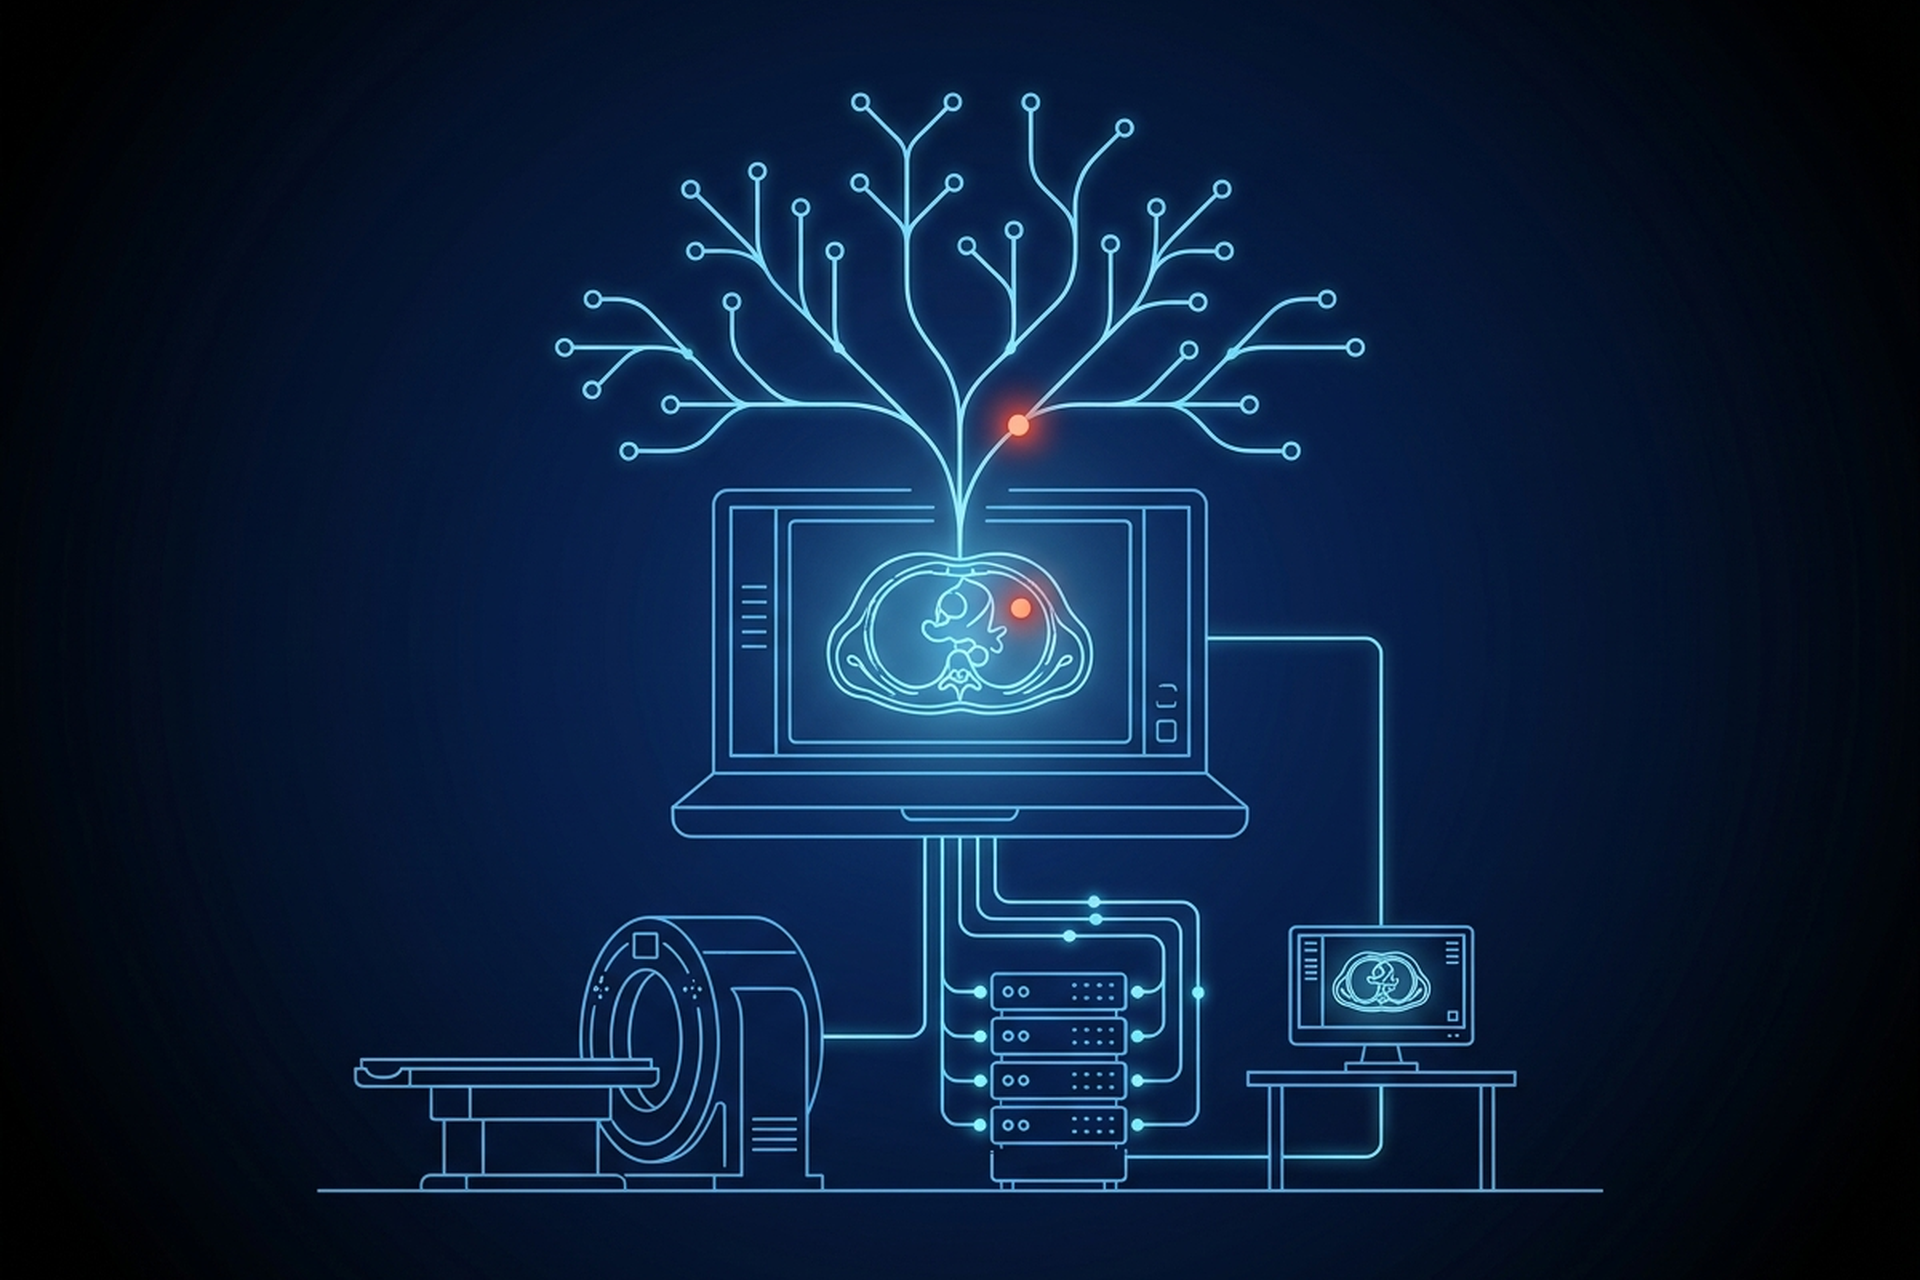
A radiologist reads a chest CT and dictates: “3.2 cm heterogeneously enhancing mass, right upper lobe, unchanged from prior.” That sentence is precise to a trained reader and opaque to almost everything else: nothing downstream can query “which patients have a mass over 3 cm” without re-reading the prose and guessing. DICOM SR, DICOM Structured Reporting, closes that gap: an SR object encodes findings and measurements as a tree of coded, machine-readable items instead of a paragraph, each tied to the exact image it came from. That is the premise, and the tradeoff is worth naming upfront: producing that tree costs a radiologist real effort at the exact moment they are trying to move fast.
What a DICOM SR Content Tree Actually Encodes
DICOM defines SR’s structure in Part 3, the volume that defines every other DICOM object. The SR Document Content Module states the shape plainly. “The root Content Item is of type CONTAINER, and its Content Sequence conveys either directly or indirectly through further nested Content Sequences, all of the other Content Items in the document.” Everything in the report nests under that root, item by item, and the root CONTAINER’s own Concept Name Code Sequence carries the document’s title.
A content item is a name and value pair, not a sentence: a concept name saying what it is, a value carrying what it says, and a relationship tying it to its parent. A Value Type attribute declares which of several defined encodings the value uses. TEXT carries a narrative fragment, CODE a coded finding, NUM a measurement paired with its unit, IMAGE a reference to another object, and CONTAINER a heading grouping more items underneath it. “Value Type (0040,A040) explicitly conveys the type of Content Item value encoding,” in DICOM’s own wording, and a parser never has to guess which one it is looking at.
Content items connect through an explicit Relationship Type, not prose. DICOM’s relationship type table defines CONTAINS for a heading holding its content, HAS OBS CONTEXT for who made the observation, and HAS PROPERTIES for a finding’s attributes. Two more matter most for anything quantitative: INFERRED FROM and SELECTED FROM, covered below. A container labeled “Findings” that contains a coded finding with properties pointing at a measurement is the same information a narrative report buries in a sentence, pulled apart into pieces a machine can traverse.
Coded Terminology: Why Codes Instead of Free Text
A TEXT content item can hold anything: “mass,” “lesion,” “suspicious area,” three radiologists’ three words for close to the same finding, while a CODE content item cannot. Its value is a fixed triple: a code value, the coding scheme that assigned it, and the human-readable meaning. Any two systems that understand the scheme resolve that triple to the same concept, whichever vendor’s software wrote or read it.
DICOM’s own worked example of transforming annotation data into SR shows this. A finding is encoded as (52988006,SCT,”Lesion”), SCT being SNOMED CT, next to a procedure code of (44136-0,LN,”PET unspecified body region”), LN being LOINC. Neither triple is open to interpretation the way “lesion” typed into a free-text field is.
Numeric values get the same treatment through a different value type. A NUM content item pairs a number with a coded unit rather than a bare figure. DICOM’s own worked example encodes 1.98024 against the UCUM code g/ml{SUVbw}, which CID 85 defines as Standardized Uptake Value body weight, not plain grams per milliliter. The annotation in braces is the whole reason that code is distinct: CID 85 lists five more SUV unit codes beside it, each pinned to a different body-size correction.
Multiply the same discipline across a report with a dozen measurements, each carrying its own coded unit. The gap between “probably millimeters” and “millimeters, encoded as such” is most of what makes an SR object queryable. Nothing downstream has to infer what a bare “1.98024” was supposed to mean.
Binding a Measurement to the Pixels It Came From
A number alone is not evidence. DICOM SR ties a measurement back to the image it was drawn from using a value type built for exactly that: SCOORD, spatial coordinates. Its definition in DICOM’s Value Type table reads: “Spatial coordinates of a geometric region of interest in the DICOM image coordinate system. The IMAGE Content Item from which spatial coordinates are selected is denoted by a SELECTED FROM relationship.”
The relationship type table gives that mechanism a worked example. A NUM content item for a biparietal diameter of 5mm carries an INFERRED FROM relationship pointing at an SCOORD, and that SCOORD carries a SELECTED FROM relationship pointing at the IMAGE it was measured on. A viewer that understands the content tree can walk from the number to that SCOORD and draw the same annotation onto the pixels, the coordinate vocabulary a DICOM viewer already uses for its measurement tools.
A measurement in a narrative report is a sentence a reader trusts because a radiologist wrote it. A measurement in an SR object is a number a system can verify, because the coordinates that produced it are encoded alongside it.
Templates and TID Families: What Actually Constrains the Tree
A tree with sixteen value types and seven relationship types can encode almost anything, which is also the problem. Two SR objects reporting the same measurement could structure it completely differently and both remain valid, defeating the purpose of encoding it at all. PS3.16, DICOM’s Content Mapping Resource, closes that gap by defining templates, each identified by a Template ID (TID), that constrain which content items, relationships, and coded values are allowed at each position in a tree.
The TID 1400 series, Linear, Area, and Volume Measurement among them, structures a single quantitative measurement regardless of which modality or algorithm produced it. TID 1500, Measurement Report, sits above that family as the umbrella template for a report built from one or more measurement groups, each a coded finding tied to its own measurements and image references. TID 1500 is general enough to cover both a human-authored report and an algorithm’s output, covered next.
A separate family, chest and colon CAD reports among them, constrains SR for computer-aided detection down to the coded vocabulary for a single finding. None of these templates changes what SR fundamentally is, only how predictable it is, which is what lets a partner’s viewer or analytics pipeline build against SR content without special-casing every vendor’s interpretation.
An SR Object Is Not a PDF Wearing a DICOM Wrapper
DICOM has a separate, simpler way to carry a report inside a DICOM object, easily conflated with SR. The Encapsulated PDF IOD does exactly what its name says: DICOM’s own description is one sentence, “The Encapsulated PDF IOD describes a PDF document that has been encapsulated within a DICOM Information Object.” That gives the PDF a Study Instance UID, ties it to a patient and accession number, and lets it move through the same DICOM services as any other object. What it does not give the report is a single queryable element inside its own content: the PDF’s text is exactly as opaque as before encapsulation, a human-readable document carrying DICOM headers.
Even the simplest SR document type carries something the PDF never will. The Basic Text SR IOD is that simplest type. DICOM’s own phrasing: “intended for the representation of reports with minimal usage of coded entries (typically used in Document Title and headings) and a hierarchical tree of headings under which may appear text and subheadings.”
Even at that minimal end, the document is built from addressable content items a system can query without opening a viewer or running OCR. The difference is not report quality, since a Basic Text SR can hold prose that reads exactly like a PDF’s; it is structure, and DICOM defines the shape of that structure.
What AI Output as SR Actually Enables Downstream
The same content tree that structures a radiologist’s measurement structures an algorithm’s output, which is why TID 1500 is the target format in DICOM’s own annotation-to-SR documentation. A worked example there shows it in practice: a measurement group carrying a coded finding, plus a tracking identifier and UID that persist across a patient’s follow-up studies. Numeric content items then carry the measured value at its minimum, maximum, mean, and standard deviation, each with its own coded derivation value saying which statistic it is.
Every piece of that is what a downstream system needs and a narrative report does not give it. A tracking UID lets a system match “this lesion” across two studies six months apart without a human deciding they match. A coded derivation value lets a system pull the maximum specifically, not parse a sentence hoping “peak” appears near the right number.
A coded finding lets a system aggregate how many an algorithm flagged this quarter, across every study it touched, without a human coding a spreadsheet by hand. All of those depend on the coding being present in the object itself, which an algorithm writing TID 1500 supplies without anyone asking.
Why SR Adoption Still Lags
None of this is hypothetical or new. DICOM has defined SR since the late 1990s, and the case for coded, queryable findings over prose has been argued in the radiology literature for almost as long without producing full adoption. The reason is not that radiologists doubt the value; it is where the cost of producing an SR object lands.
A 2009 editorial in the Journal of Digital Imaging names the pattern directly. “Structured reporting was created in the hopes of addressing well-documented deficiencies in report content and organization but has largely failed in its adoption due to concerns over workflow and productivity.” The same piece is specific about whose concerns those are: “The radiologist community has been relatively recalcitrant to reporting changes and is, to a large extent, driven by concerns over workflow and productivity optimization.”
Dictating a sentence into a microphone is fast. Selecting a coded finding from a controlled vocabulary and attaching a coded unit to every measurement is not. Not when a human does the selecting, one content item at a time, while trying to finish a study and move on.
That is also why the SR objects that spread fastest are the ones a human never has to hand-author. An algorithm producing TID 1500 output pays the structuring cost once, in software, and produces the same coded tree every time without a radiologist touching anything. A quantification tool that writes SCOORD-anchored measurements as a byproduct of a click a radiologist was already making, drawing a region of interest for a number on screen, gets SR for free.
What This Means for Your Evaluation
For a product or engineering team scoping whether a platform actually speaks SR, itemized questions serve better than “does it support structured reporting” as a yes-or-no. Does it read and write the value types it needs, TEXT and CODE at minimum, NUM and SCOORD if measurements matter? Does it constrain output to a named template, TID 1500 or a relative, or write an ad hoc tree no other vendor’s parser has seen?
Does a measurement carry an SCOORD anchor back to the image, or arrive as a bare number with no way to verify where it came from? And does the platform tell an SR object apart from a PDF that merely looks like a report?
EBM mAIn PACS® offers the native DICOM services an SR object travels on: C-STORE to store one, Query/Retrieve to pull one back, Storage Commitment to confirm it saved. Those services carry any composite instance, not pixel data alone, but a C-STORE is negotiated per SOP Class, and Basic Text SR, Enhanced SR and Comprehensive SR are each a separate one. DICOM’s Storage Service Class states the condition plainly: a successful C-STORE means “Both the SCU and the SCP support the type of information to be stored.”
Which SR SOP Classes a given archive accepts belongs in its conformance statement, which is the document to ask for rather than assuming an SR document routes exactly like a CT series. Above transport sits a separate layer: parsing the content tree and rendering an SCOORD-anchored measurement back onto its image, work covered in DICOM Viewers: How Clinicians Open, Read, and Measure a Study. Moving the object and reading its content are different capabilities, worth pressing any vendor on before assuming one implies the other.
SR content deserves a second look before it travels outside the system that produced it. A structured report’s Content Sequence can carry an observer’s name or other identifying content the same way a study’s image data can, a risk covered in Removing PHI From a Study Without Breaking It. An SR object is not automatically safer to share than a narrative report just because it looks more like data.
Getting a finding into a form software can act on was never a rendering problem. It is a modeling problem DICOM solved two decades ago, and one the industry is still deciding, report by report and algorithm by algorithm, whether the structuring cost is worth paying.